
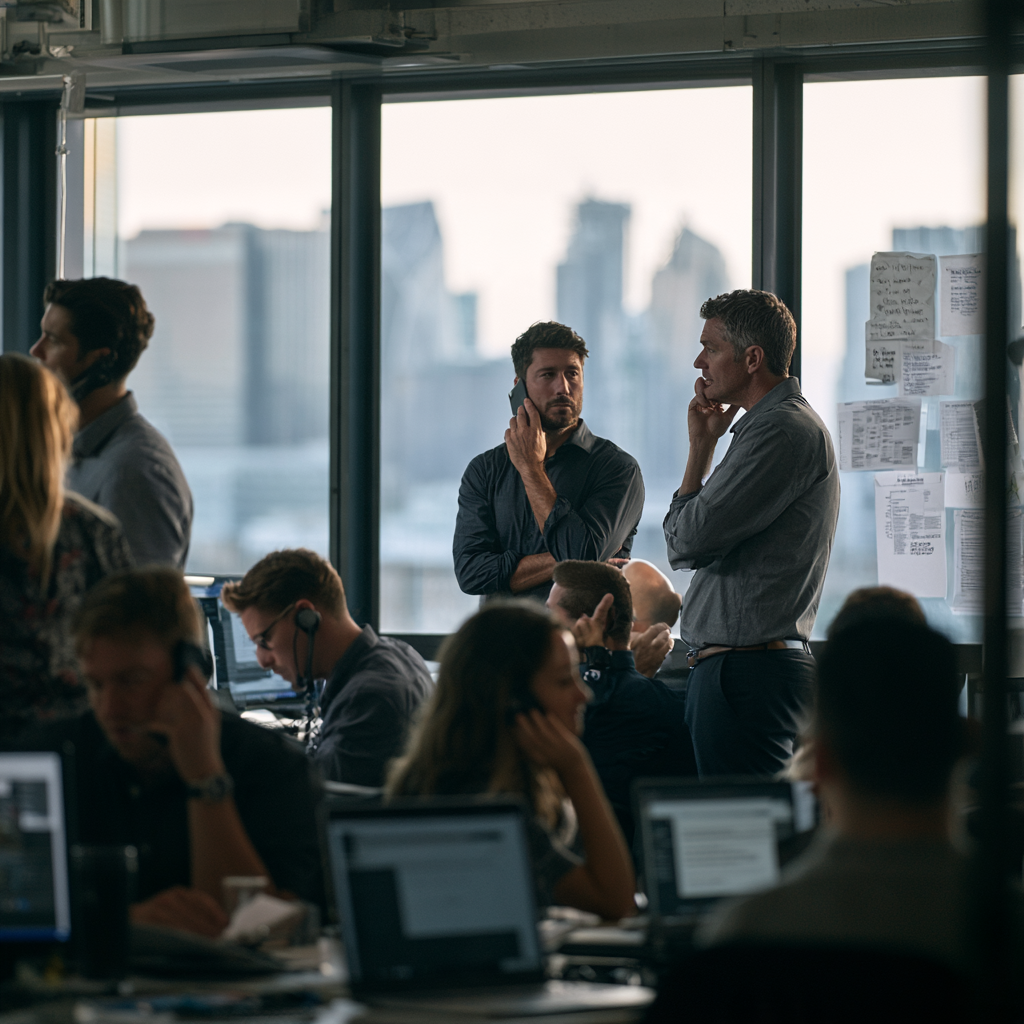
Write this date down Friday the 13th November 2026. Those of us in IT will remember this date for years to come. The one event we always said could never happen, happened. For more than a day, one of the world’s most important workplace technology platforms had serious problems.
Outlook stopped behaving like Outlook. Teams was disrupted. Calendars became unreliable. Emails sat somewhere between sender and recipient. Copilot and other Microsoft 365 services were affected.
Reuters reported that the disruption lasted more than 24 hours, affecting businesses and government agencies around the world. Downdetector recorded more than 7.4 million reports globally.
This was not a theoretical disaster recovery exercise held in a meeting room on a Tuesday afternoon. It was the real thing. And nobody had scheduled it.
At first, there was the usual reaction
Is Outlook down for you?
Try restarting it.
Teams isn’t working either.
Have you tried the browser?
It must be our network.
Then somebody checks Microsoft Service Health.
Suddenly a local IT problem becomes something much more interesting.
How does our business operate when the technology we normally depend on simply isn’t available?
That is where an outage stops being an IT incident and becomes a business continuity test.
Having a business continuity plan is not the same as being able to continue business
Most reasonably mature organisations have continuity documents.
There will be recovery procedures, RTOs, RPOs, escalation paths, critical application lists, contact trees and probably a very impressive diagram showing how everything fits together.
All useful.
But the Microsoft outage asked a much simpler question.
Can your people still do their jobs?
If Outlook is unavailable, how do you communicate with customers?
If Teams is unavailable, where do operational conversations move?
If Exchange Online is affected, can staff access the information required to make decisions?
If the normal collaboration environment is unavailable, can executives still communicate with each other?
If your crisis communications plan itself depends on Microsoft 365, how do you activate it?
That last one is worth thinking about.
The problem is not Microsoft
It would be easy to turn this into an argument about Microsoft reliability, but I don’t think that is the interesting lesson.
Microsoft said the outage was not the result of malicious activity. AP (Associated Press) reported that Microsoft attributed the incident to an earlier network capacity upgrade, with the problem surfacing following a more recent network change. We have all been in the deep end when complex technology fails.
Amazon Web Services fails.
Telecommunications providers fail.
Data Centres fail.
Applications fail.
Networks fail.
People certainly fail.
The purpose of resilience is not to find technology that will never fail.
It is to design a business that can tolerate failure when it inevitably happens.
We have quietly created enormous concentrations of dependency
Twenty years ago, many organisations had separate systems for email, telephony, document storage, conferencing, collaboration and identity.
That was not necessarily better. In many cases it was expensive and difficult to manage. Then cloud platforms arrived and transformed that model. Today a single ecosystem can provide identity, email, meetings, messaging, document collaboration, workflow, security and increasingly everyday automation.
The benefits are enormous, but with benefits so comes the concentration risk.
AP reported that the outage affected governments, courts, healthcare organisations, airlines, banks and businesses. It also noted that Microsoft says more than 430 million people use Microsoft 365 applications. That scale is extraordinary.
But there is another question organisations should ask themselves.
How many of our supposedly independent business processes ultimately depend on the same piece of infrastructure?
That answer can be uncomfortable.
A backup isn’t necessarily a workaround
This is something I see regularly when talking about technology resilience. Ask whether a critical system is protected and the answer is often/
Yes of course, it’s backed up.
Good, but backup and continuity solve different problems. A backup helps you recover information, whilst a continuity capability helps you keep operating.
If Exchange Online is unavailable for eight hours, restoring yesterday’s mailbox backup doesn’t necessarily help your sales team communicate with customers today.
If Teams is unavailable, having copies of the documents stored elsewhere doesn’t tell your workforce where to communicate.
The practical question isn’t simply –
Can we recover our data?
It is:
Can we continue delivering our service?
Those are very different tests.
So run the Microsoft test yourself
You don’t need a sophisticated simulation. Pick a morning and ask your leadership team.
Microsoft 365 has just disappeared. Assume it will not return until tomorrow morning. What happens next?
Then work through the business.
No Outlook. No Exchange Online. No Teams. Oh and assume some SharePoint-dependent processes are unavailable too.
Now ask:
- How do we contact our people?
- How do our people contact each other?
- How do customers contact us?
- Which revenue-generating activities stop?
- Which operational processes stop?
- Which safety, regulatory or customer obligations could be affected?
- Where are the alternative procedures stored?
- Can people access those procedures without Microsoft 365?
- Who has authority to invoke the workaround?
- Has anybody actually tested it?
Give the team 30 minutes. You may learn more about your resilience in those 30 minutes than you will from reading a 70-page continuity plan.
Don’t immediately reach for multi-cloud
There is a temptation after every major cloud outage to declare.
We need another cloud.
Perhaps, but what scenario are you trying to resolve?
Running fully redundant Microsoft and Google or Azure and AWS environments can introduce considerable cost, operational complexity and another collection of things capable of going wrong.
Resilience needs to reflect business impact, not architectural enthusiasm.
I do not disagree, for some processes, the appropriate answer might be a second platform, but for others, it could be an independent communications channel.
For another, an offline copy of essential information may be enough, and sometimes the correct continuity solution is surprisingly low-tech.
A telephone number that people actually know can be remarkably resilient.
The board-level question has changed
For years executives have quite reasonably asked CIOs.
Are our systems resilient?
I am sure the answer has always been ‘Of course’ we have backups or we have a Disaster Recovery service, but I think there is now a better question.
If our major technology providers disappeared for a working day, or longer, could we still operate the business?
That moves the discussion away from server uptime and into customers, revenue, operations, people and reputation. Which is exactly where business continuity belongs.
The Microsoft outage eventually ended. Services were restored and for thousands of organisations, however, something valuable happened while the engineers were fixing it. They received a genuine test of their business continuity arrangements.
No consultants arranged it and nobody rehearsed for it. There were no carefully written exercise injects and Microsoft provided the perfect scenario.
The interesting question is whether we are prepared to learn from the results.
The Summary
The recent Microsoft outage was more than a technology failure, it was an unscheduled business continuity test that exposed how dependent many organisations have become on a single technology ecosystem.
Real resilience is not about preventing every outage, but ensuring your business can keep serving customers, making decisions and communicating when critical technology disappears.
About Bushey
Bushey is a technology transformation consultancy helping organisations deliver complex change with greater control, confidence and accountability.
We work on the client side, bringing together business, technology, governance and delivery to ensure transformation achieves the outcomes it was intended to deliver. Our services span Technology Transformation, Artificial Intelligence, Cybersecurity, Data Centre and infrastructure, M&A technology integration and separation, resilience, Disaster Recovery, programme assurance and governance.
Our AssureChange® framework provides a structured approach to project delivery, change and governance, while BAIGS® helps organisations establish practical governance for the responsible adoption and management of AI.
From major technology programmes to individual areas of risk or change, Bushey provides experienced leadership, independent oversight and hands-on delivery to help organisations turn strategy into measurable business outcomes.
#BusinessContinuity #OperationalResilience #Microsoft365 #RiskManagement #DigitalResilience
Comments are closed